Multi-Site Maintenance Management: How to Standardise Without Losing Local Control

What is multi-site maintenance management?
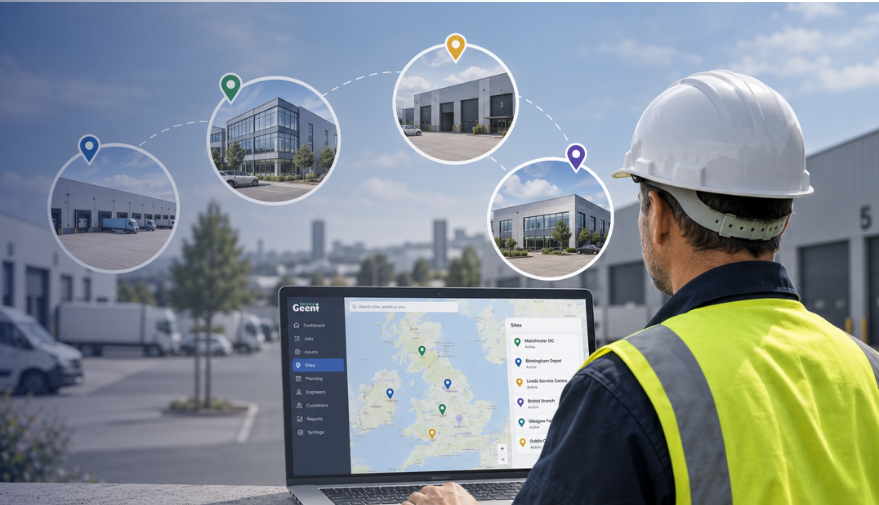
Multi-site maintenance management is the practice of planning, delivering and reporting maintenance across two or more locations using shared standards and one source of asset data. It normally covers:
- Preventive maintenance schedules for equipment at every site
- Reactive work orders raised by production, warehouse or facilities staff
- Asset registers, service histories and condition data
- Spares and stock held across multiple stores
- Statutory inspection and compliance evidence
- Engineer time, whether based on one site or covering several
This sits in CMMS territory rather than field service, because the engineers are internal and the assets belong to the business. There is crossover, though. Once a maintenance team travels between locations, the planning problem starts to look a lot like field service scheduling, which is why some multi-site operations end up needing capabilities from both worlds.
Why managing maintenance across multiple sites breaks down
Multi-site maintenance usually fails for reasons of structure rather than effort. Five patterns come up repeatedly.
Every site invents its own naming conventions
One depot logs a machine as "Conveyor 3". Another calls the same model "CNV-03-LINE2". A third records it against the building rather than the asset. Nothing is technically wrong, and none of it can be compared. Failure codes drift in the same way, so the reasons behind breakdowns stop being countable.
Monthly reporting becomes a reconstruction exercise
When each location keeps its own spreadsheet or its own instance of a system, head office reporting turns into a chase for data instead of an analysis of it. By the time the numbers arrive they are weeks old, definitions vary, and nobody trusts the comparison enough to act on it.
Good practice stays trapped at one location
A site fixes a recurring hydraulic fault by adjusting its PM interval and adding two checks to the task list. That knowledge lives in one team's heads. Without a shared task library there is no route for the fix to reach the other nine sites running identical equipment.
Compliance evidence is only as strong as the weakest site
Statutory inspection regimes do not flex according to how organised a location happens to be. Thorough examination of lift trucks, for example, is a legal requirement under LOLER and PUWER, and the HSE is explicit that routine inspections under a preventive maintenance scheme or scheduled service do not count as a thorough examination. If certificates sit in a filing cabinet at one site and a shared drive at another, the estate has a reporting problem and a risk problem at the same time.
The cost of inconsistency only shows up in aggregate
Individual sites tend to absorb downtime as a fact of life. Viewed across an estate the figure is harder to ignore. Modelling from IDS-INDATA projects that manufacturers across the UK and Europe will lose between £124bn and £157bn to unplanned downtime in 2026 across nine sectors, with recovery time now a key cost multiplier alongside incident frequency. ABB's global study of 3,600 senior decision makers found 44% experience equipment-related interruptions at least monthly, with 14% reporting stoppages every week. Sites that cannot see each other's failure history keep solving the same problems separately.
What to standardise across locations, and what to leave alone
The useful question is not how much to standardise. It is which decisions need to produce comparable data and which decisions only affect how a site gets through its week.
Standardise centrally
- Asset naming and hierarchy. One convention, applied estate-wide, with each asset tied to a site and a location within that site.
- Asset criticality definitions. A "critical" asset should mean the same thing in Derby as it does in Dundee.
- Work order types and priority levels. Enough categories to be meaningful, few enough that engineers pick the right one.
- Failure and cause codes. The shortest workable list. Long lists get ignored or guessed at.
- Mandatory fields on completion. Labour time, parts used, cause of failure, downtime duration.
- PM task content for shared equipment types. The checks themselves, along with any safety-critical steps.
- Compliance records and certificate storage. Same format, same place, retrievable without ringing a site manager.
Leave to individual sites
- When PMs are scheduled. A site running three shifts and a site running one need different windows.
- Who does the work. Local engineer allocation, contractor choice and skills matching.
- Task sequencing within a shift. Sites know their own access constraints and production plans.
- Local spares holdings above the agreed minimum. Sites carry risk differently depending on distance from suppliers.
- Day-to-day prioritisation between jobs of equal severity. Someone on the ground will always judge this better.
The test for anything in between
If a decision changes what a number means, it belongs to the centre. If it only changes how a site gets the job done, leave it local. That single rule resolves most arguments about templates, and it keeps work order management consistent without dictating a site's daily routine.
What a multi-site CMMS needs to do
Standards hold only when the system makes following them the path of least resistance. A multi-site CMMS should handle five things well.
A single asset register with a site hierarchy
Every asset should exist once, tied to its site and its own service history. Asset-centric record keeping is what makes cross-site comparison possible, because you can look at the same machine model across ten locations and see which sites are getting more life out of it. Site-based record keeping cannot answer that question.
Shared PM libraries with local calendars
Central task libraries mean the checks are identical everywhere, while sites keep control of scheduling. When a task gets improved, the update reaches every location running that equipment. This is the practical mechanism for spreading good practice, and it is a core function of planned preventive maintenance at scale.
Permissions that match responsibility
Site engineers need their own site. Regional managers need a group of sites. Head office needs the estate. Getting this right removes the two most common complaints at once: engineers wading through irrelevant jobs, and managers unable to see beyond their own four walls.
Stock visibility across stores
Knowing that a part sits at a site 40 miles away is often the difference between a two-hour fix and a two-day wait. Shared visibility also stops the estate holding the same slow-moving spare in eight separate stores.
Route planning for engineers who cover several sites
Many multi-site operations run a mobile maintenance team alongside site-based engineers. Specialists cover a region, statutory inspections are batched into circuits, and someone has to work out the driving. Manual planning tends to default to geography and habit rather than priority. AI route optimisation handles the same problem field service teams face, weighing skills, site priorities and travel time together. This is the point where multi-site maintenance genuinely borrows from field service software.
How to standardise maintenance across locations
Standardisation programmes stall when they try to fix everything at once. A sequence that works:
- Pick a reference site. Choose the location with the most reliable data, not the biggest. Use it to build the templates.
- Agree the non-negotiables. Asset naming, criticality, work order types, failure codes, mandatory completion fields. Keep the list short enough to explain in a single meeting.
- Clean asset data before migration. Walking the site with a phone and a QR label beats importing a decade of spreadsheet errors.
- Build the shared PM library. Group by equipment type rather than by site. Let sites set their own dates.
- Roll out in waves. Two or three sites at a time, with a review between waves. Early sites become the people who train later ones.
- Measure adoption before performance. Work order completion rates and data completeness tell you whether the standards are holding. Downtime figures mean nothing until they are.
Two things are worth planning for. The first is resistance from sites that already work well, which is usually best answered by showing what they gain rather than what head office needs. The second is capability. Fluke's May 2026 survey of 600 maintenance decision makers across the UK, US and Germany found that skills-related challenges accounted for roughly 78% of all reported obstacles to digital maturity, including gaps in expertise, knowledge and skilled labour. Standard templates and embedded work instructions help here, because they reduce how much any individual engineer needs to carry in their head.
The metrics that make sites comparable
Once definitions are shared, a small set of measures does most of the work:
- PM completion rate and schedule compliance
- Planned versus reactive work ratio
- Mean time to repair and mean time between failures, by asset type
- Backlog size and backlog age
- Maintenance cost per asset and per site
- Downtime hours attributable to equipment failure
Six measures applied consistently beat 30 measures that mean different things in different places. For how to structure this for board and regional reporting, see our guide to maintenance reporting across multiple sites.
When you have outgrown your current setup
Common signals that spreadsheets or a single-site system are holding you back:
- Reporting requires manual consolidation from more than one source
- Sites cannot see each other's asset histories or stock
- Compliance certificates live in different places at different locations
- Adding a site means adding another system or another spreadsheet
- You cannot answer which asset type causes the most downtime across the estate
If several of these apply, the question becomes one of system architecture. Our comparison of multi-site CMMS versus single-site CMMS covers what changes when you move up.
Frequently asked questions
Is multi-site maintenance a CMMS or a field service problem?
It's a CMMS scenario, not a field service one: your engineers work for the business, on assets it owns, which is the core definition of maintenance management software. The exception is engineers who travel regularly between your own sites, where a multi-site CMMS needs field service's scheduling logic." - the main change being switching "problem" to "scenario
How many sites before you need a multi-site CMMS?
Site count matters less than reporting demands. Two locations sharing engineers and spares will feel the strain faster than five independent sites that never interact. The trigger is usually the first time someone asks a question about the whole estate that nobody can answer without a week of spreadsheet work.
Can you standardise without controlling site budgets?
Yes. Data standards and budget authority are separate questions. Sites can keep spending decisions while still naming assets the same way and completing work orders to the same specification. Standardising the data layer is what makes devolved budgets defensible, because you can finally see what each site is getting for its money.
How long does standardising maintenance across locations take?
For a mid-sized estate, expect three to six months to reach consistent data across all sites, with the majority of that time spent on asset data quality rather than software configuration. Sites brought on in later waves typically go live faster than the first.
Bringing it together
Standardisation works when it targets the data rather than the day. Fix asset naming, criticality, work order structure and completion fields centrally, and you get an estate you can compare, benchmark and improve. Leave scheduling, sequencing and local judgement with the people who understand their own site, and you get a system engineers will keep using. Service Geeni's CMMS is built around individual assets rather than sites, which is what makes cross-site visibility work in practice across warehouse, manufacturing and material handling operations.
Download Full PDF
Read More…
Book Your Demo Today